Blog

Build a sitemap in Web Scraper’s new side panel

November 15, 2026

Web Scraper extension, data extraction, Advanced Sitemap Builder, Side panel
Web Scraper’s Advanced Sitemap Builder is now available in the browser side panel, alongside the Sitemap Wizard. You can configure navigation, add fields and check selectors with the source website beside the builder, without opening Developer Tools.

This walkthrough follows the new demo to build a reusable sitemap that moves through categories and subcategories, handles pagination and collects data from individual item pages.

Continue Reading

Web Scraper explained: current features and capabilities

November 12, 2026

web scraper, web scraping tools, Web Scraper Cloud, AI search
Web Scraper is the point-and-click web scraping tool at webscraper.io. It combines a free browser extension for building and running scrapers locally with Web Scraper Cloud, a paid, enterprise-ready platform for scheduled jobs and workloads spanning many millions of pages.

You can create scrapers visually, extract content loaded by JavaScript and export structured data. The sections below explain the current capabilities and link to the official sources for setup, browser support and automation.

Continue Reading

Web Scraper 1.114.4: extension redesign and new tools

November 12, 2026

Web Scraper extension update, Product updates, Sitemap builder
Web Scraper extension 1.114.4 introduces a redesigned interface and brings Advanced sitemap creation into the browser sidepanel alongside the Sitemap Wizard. The release also adds a dedicated Click Once selector and improvements to selector editing, start URL import and testing.

Continue Reading

Black Friday price tracking: is the deal worth it?

November 05, 2026

price monitoring, e-commerce data, web scraping, Black Friday, price history
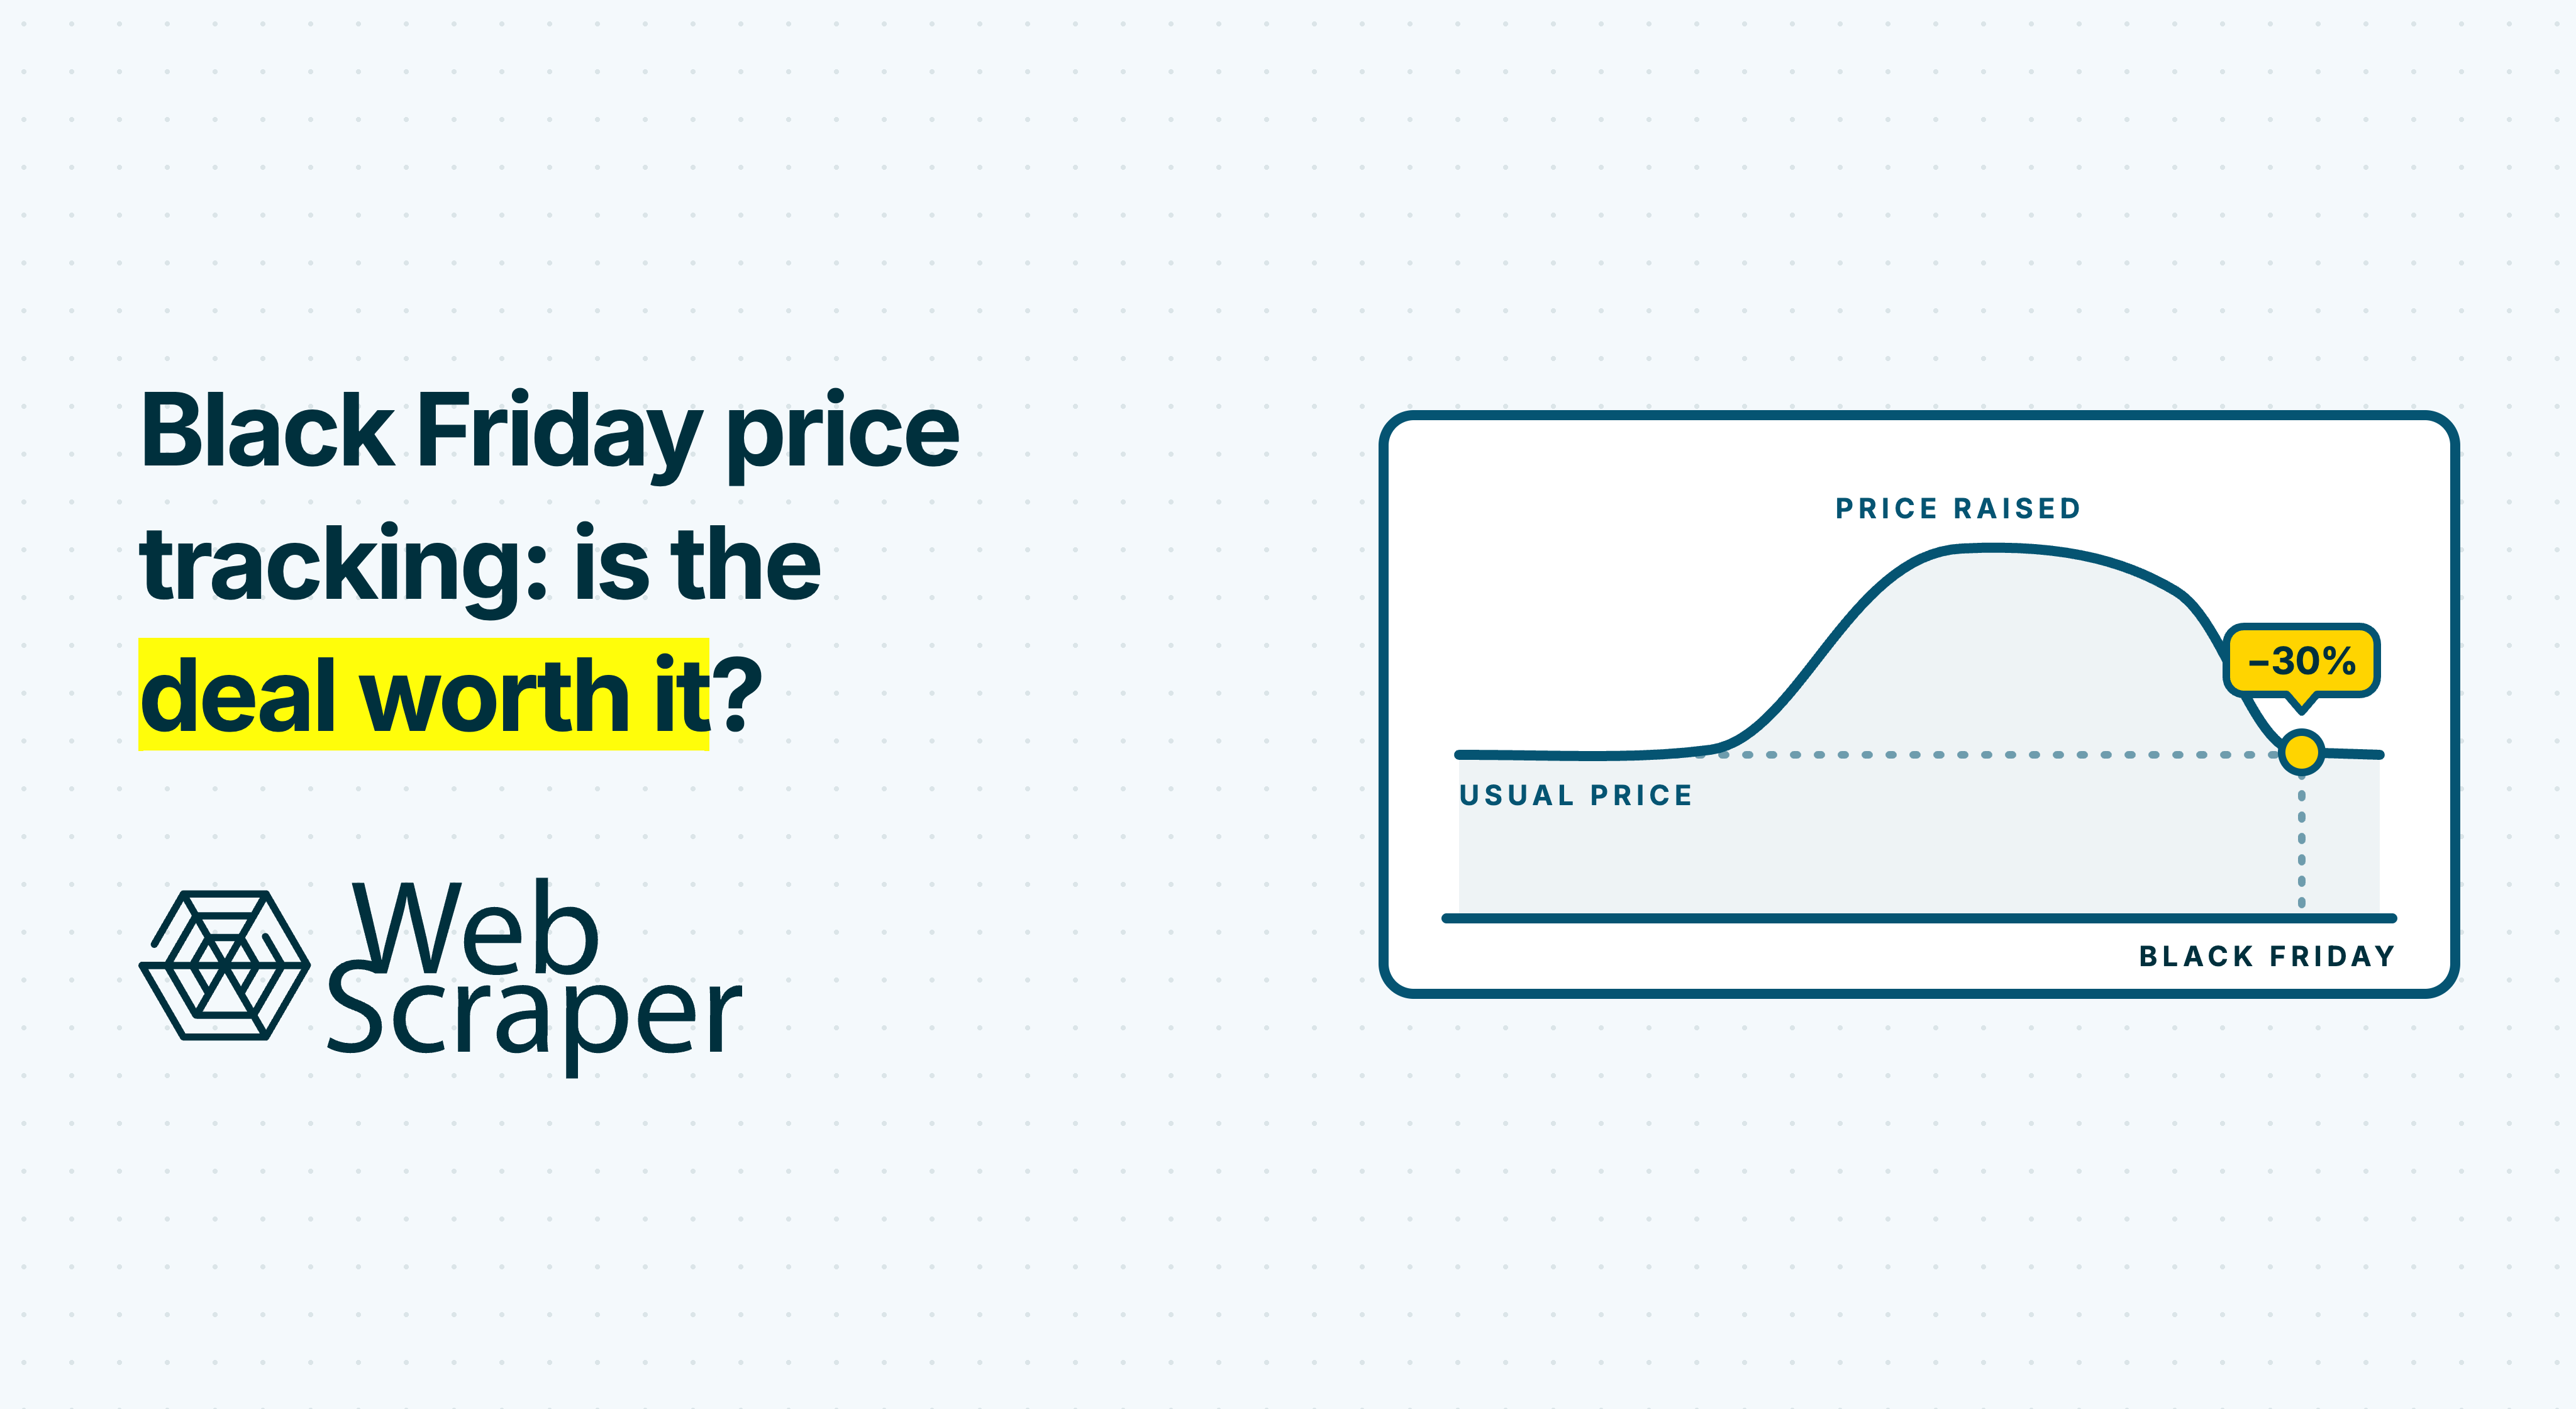
Check a Black Friday discount against the exact product's earlier prices and other sellers' current delivered totals. The percentage beside a crossed-out price tells you how two displayed numbers compare. It does not establish what the product usually cost or whether another shop offers better value today.

Black Friday price tracking gives pricing, procurement and e-commerce teams evidence for that decision. A useful result states the saving, the comparison period and any gaps in the history.

Continue Reading

Can AI shopping agents actually read your product pages?

November 04, 2026

structured data, product variants, e-commerce data, AI shopping agents, data quality
AI shopping agents can read product pages, but the information they obtain depends on the route they use. Returned HTML, a rendered browser page and a merchant feed can expose different facts about the same product.

For retailers, the useful test is whether that route supplies the right variant, applicable price, stock status and purchase conditions. Seeing your product name in an AI answer establishes very little about the rest of the offer.

Continue Reading

Scraping product reviews: build a feedback dataset

November 02, 2026

e-commerce data, Product reviews, data quality, web scraping, dataset design
Scraping product reviews gives you useful customer feedback when each review retains its product identity, source, publication date and collection context. Text and star ratings alone cannot tell you whether a complaint is new, duplicated across retailers or about a different variant.

Define the records and coverage before building the scraper, so recurring exports can preserve changes without counting the same feedback repeatedly.

Continue Reading

Why can't your scraper see content inside an iframe

November 01, 2026

web scraping troubleshooting, data quality, browser automation, CSS selectors, Iframe scraping
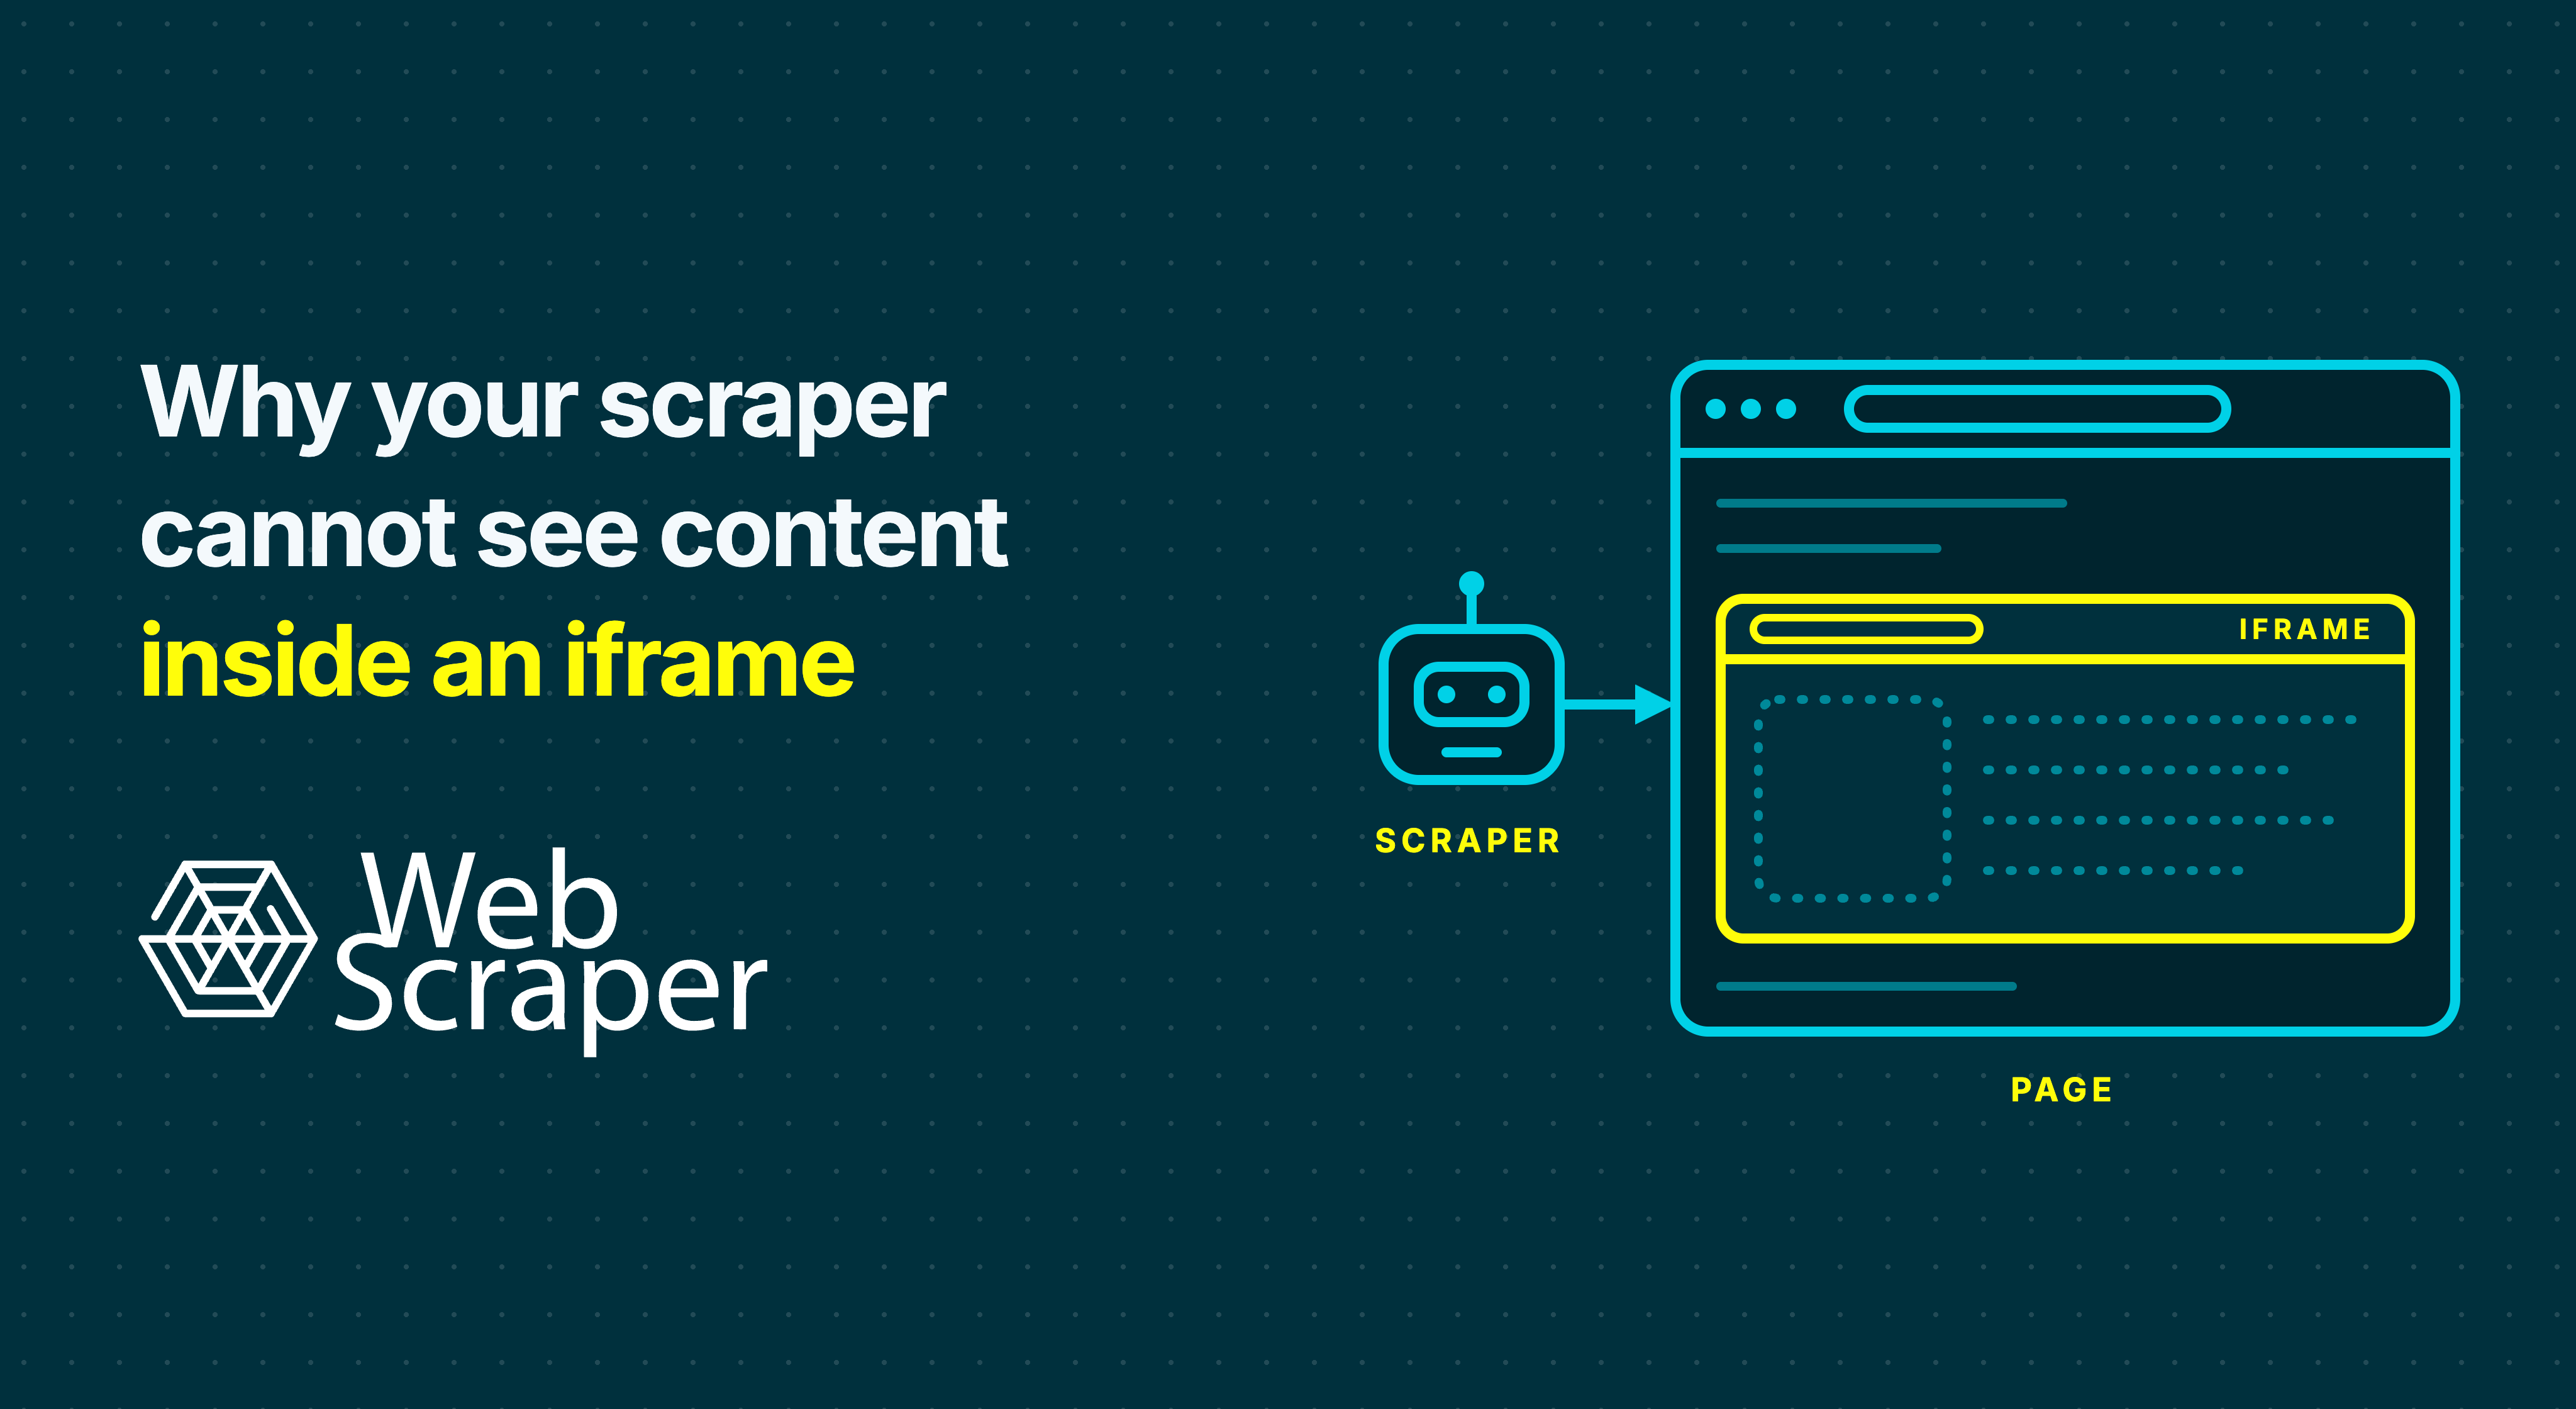
An iframe displays another document inside the page you are viewing. Your browser can show its content while a scraper searching only the surrounding document finds nothing. To scrape iframe content, identify the frame, check whether its data is ready and accessible, and choose an extraction route your tool supports.

Continue Reading

Robots.txt AI training opt-out: what the proposal changes

November 01, 2026

data governance, robots.txt, crawler controls, web scraping, AI training
A proposal published on 30 October 2026 would let websites express an AI-training preference to several providers through one shared robots.txt group. That could reduce the work of maintaining a separate opt-out for every company.

The mechanism remains an individual Internet-Draft. Providers have announced different rollout schedules, with different consequences for training and AI answers. Website owners should review those differences before replacing controls they currently rely on.

Continue Reading

AI browser traffic jumped 4.7×. What does that mean for web scraping?

October 29, 2026

crawler identity, bot detection, AI agents, AI browser traffic, web scraping
DataDome’s report published on 15 October 2026 recorded a 4.7× rise in agentic browser requests across its network in September.

For web scraping teams, this raises a practical question: how does a website distinguish an assistant checking a product from a search crawler indexing it or a company collecting its price every morning? Those activities can overlap. Sites need evidence about the operator and its behaviour, then a policy for the requested activity.

Continue Reading

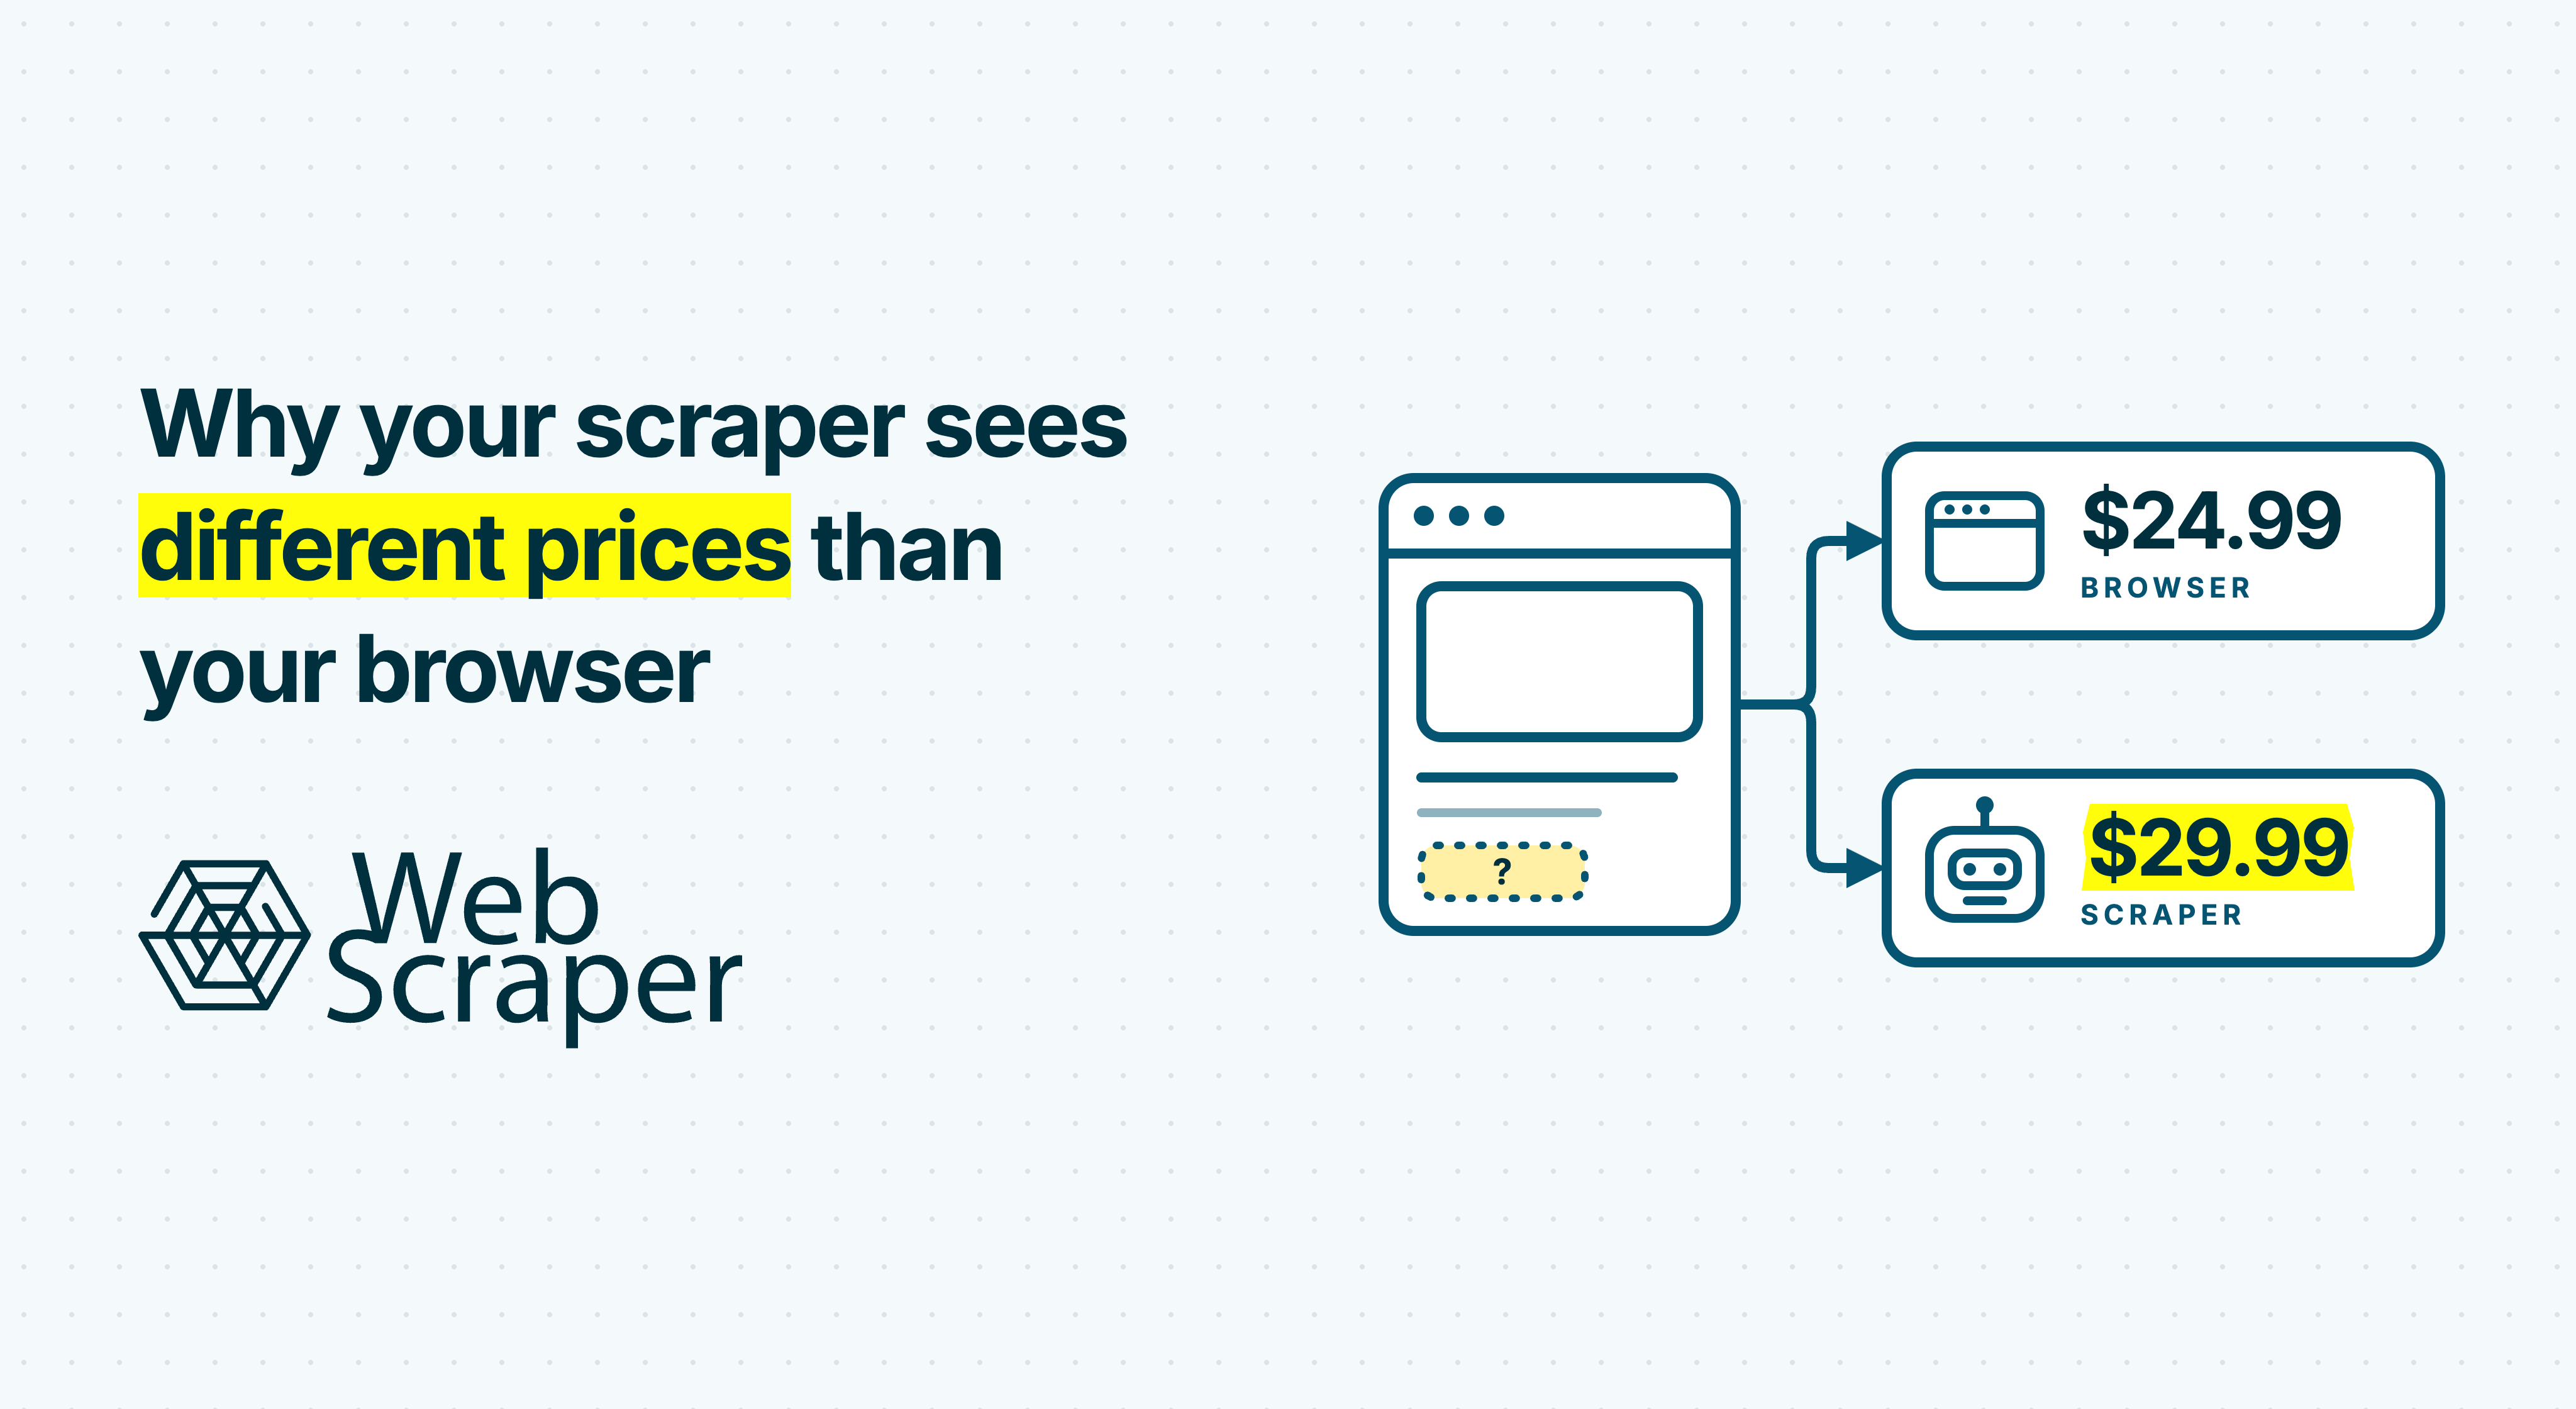
Why your scraper sees different prices than your browser

October 28, 2026

price monitoring, e-commerce data, data quality, scraping troubleshooting, browser state
Your scraper can return a different price because it receives a different offer, extracts the wrong price from the page, or changes a correct value during processing. Location, saved preferences, login state and selected variants can all affect the comparison.

Start with one mismatched product and find where the two results first diverge. That tells you what to fix before you change proxies, selectors or delays across an entire catalogue.

Continue Reading

Reddit login restrictions: when search sends fewer readers

October 27, 2026

Reddit, Data licensing, AI search, Search referrals, Public web data
Reddit plans to test login restrictions in selected markets outside the US in Q4 2026. Announced on 29 October 2026, the move comes as the platform reports falling search referrals and tries to turn more visitors into regular, signed-in users.

For teams collecting public web data, the wider risk is that fewer referral visits could give websites another reason to restrict access. Content can remain useful to an AI search service even when fewer readers visit its source.

Continue Reading

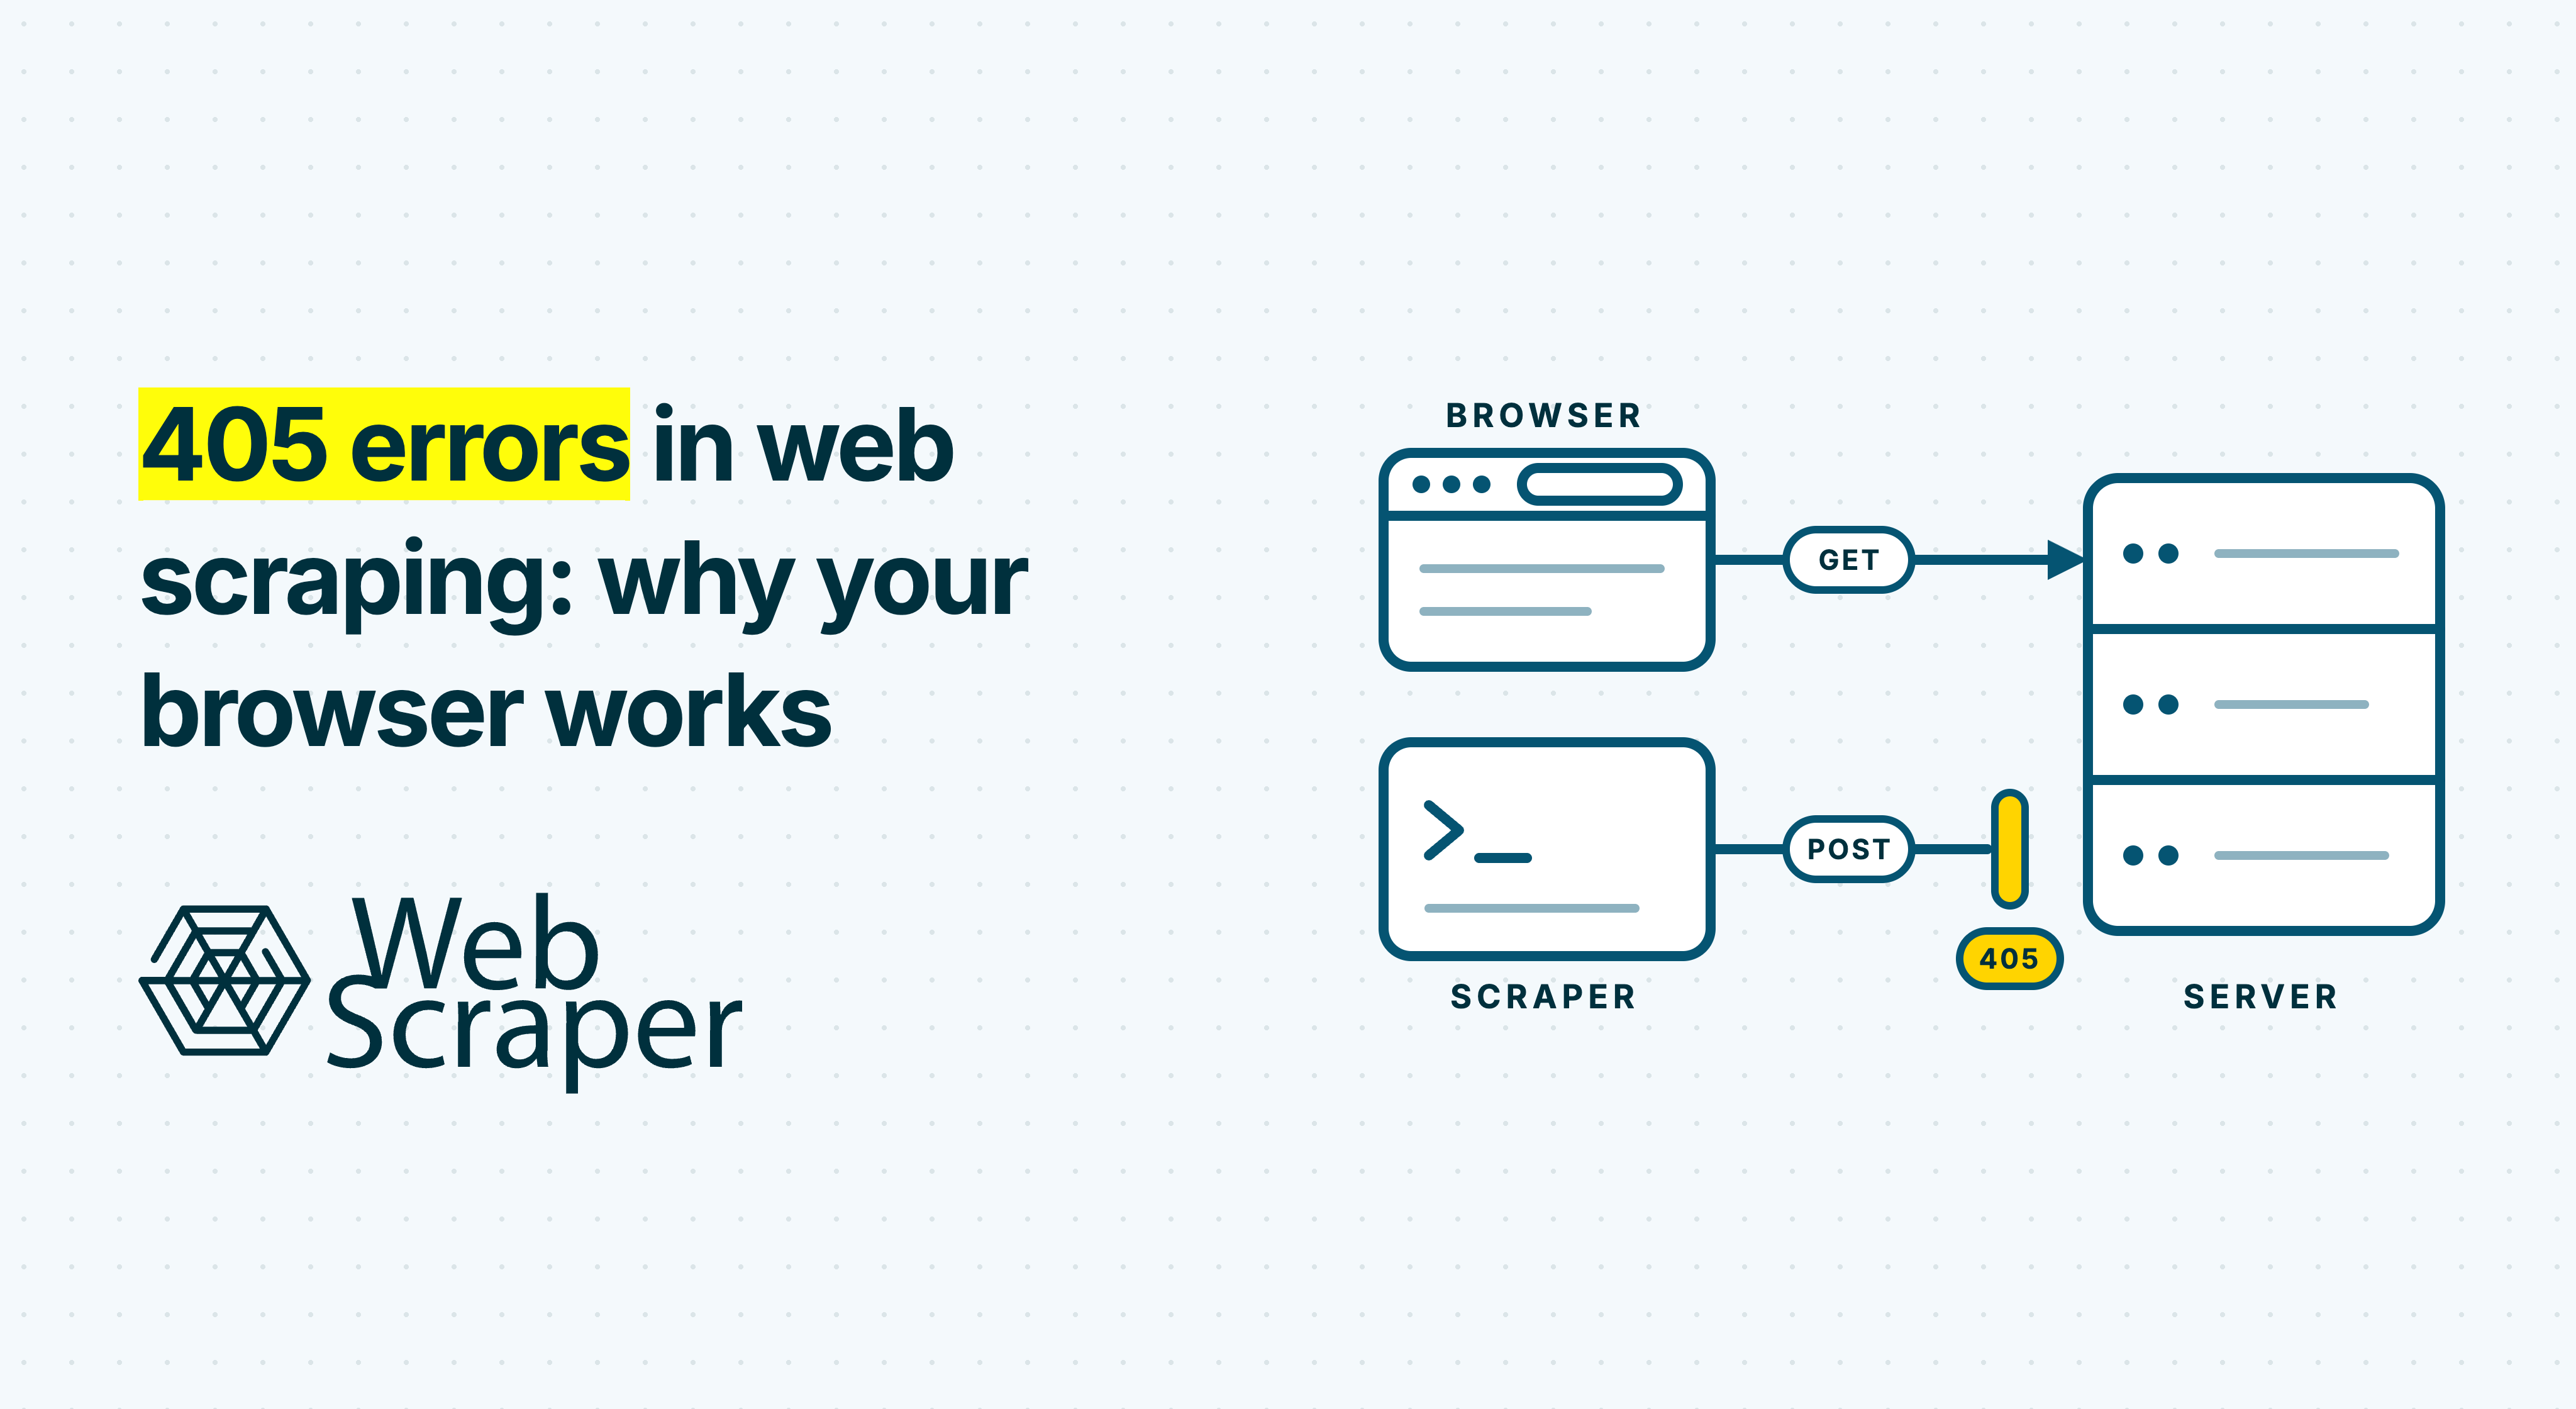
405 errors in web scraping: why your browser works

October 27, 2026

web scraping troubleshooting, Web Scraper Cloud, bot challenges, browser sessions, HTTP errors
A 405 Method Not Allowed response normally means that the requested resource does not support the HTTP method used. During web scraping, a security layer can also return 405 before the request reaches the page. AWS WAF, for example, uses this status for its CAPTCHA action.

The page opening in your browser does not settle which explanation applies. Your browser may send a different request, carry accepted session state or complete a verification flow. Compare the actual requests and responses before changing the scraper.

Continue Reading

Best web scraping tools for handling anti-bot protection

October 24, 2026

web scraping tools, Web Scraper Cloud, scraping costs, residential proxies, anti-bot protection
For recurring product catalogues, marketplace listings, property data and business directories, Web Scraper Cloud is our best-value starting point. It combines managed anti-bot handling with structured extraction, scheduled collection and delivery in one platform.

Residential proxy pricing is one of the first things to compare. A low subscription price can become a substantial operating bill when a protected scraping job transfers hundreds of gigabytes. This guide compares eight tools by their access capabilities, billing models and the work needed to deliver a usable dataset.

Continue Reading

Best web scraping tools for niche websites

October 16, 2026

data extraction, web scraping tools, Web Scraper Cloud, custom sitemaps, product data
The best web scraping tools for niche websites let you define the extraction when a ready-made scraper does not cover your source or required fields. For operations teams building recurring structured datasets without writing scraper code, Web Scraper is our recommended starting point.

Think specialist supplier catalogues, regional retailers, industry directories and smaller job boards. Octoparse, ParseHub, Browse AI and Apify also offer custom setup routes. The useful comparison is what your team can configure, validate and maintain after a template search comes up empty.

Continue Reading

Researchers got AI search engines to cite a made-up concept

October 15, 2026

market research, data quality, source verification, AI search, web scraping

Researchers published material about a fictional “Cactus Gravity Protocol” and saw it cited by eight of ten tested AI search platforms, including ChatGPT and Perplexity, within seven days. For businesses using AI to investigate markets or suppliers, the result raises a practical question: what does a citation actually prove?

Continue Reading